

Irrational Analysis is heavily invested in the semiconductor industry.
Positions will change over time and are regularly updated.
Opinions are authors own and do not represent past, present, and/or future employers.
All content published on this newsletter is based on public information and independent research conducted since 2011.
This newsletter is not financial advice and readers should always do their own research before investing in any security.
Feel free to contact me via email at: irrational_analysis@proton.me
Hello everyone. Very excited to share an updated view on Cerebras. A lot has changed.
You can find the report in PDF format attached here.

For this special occasion, I made this report using LaTex (TeXstudio+MiKTeX). This is what the editor looks like.
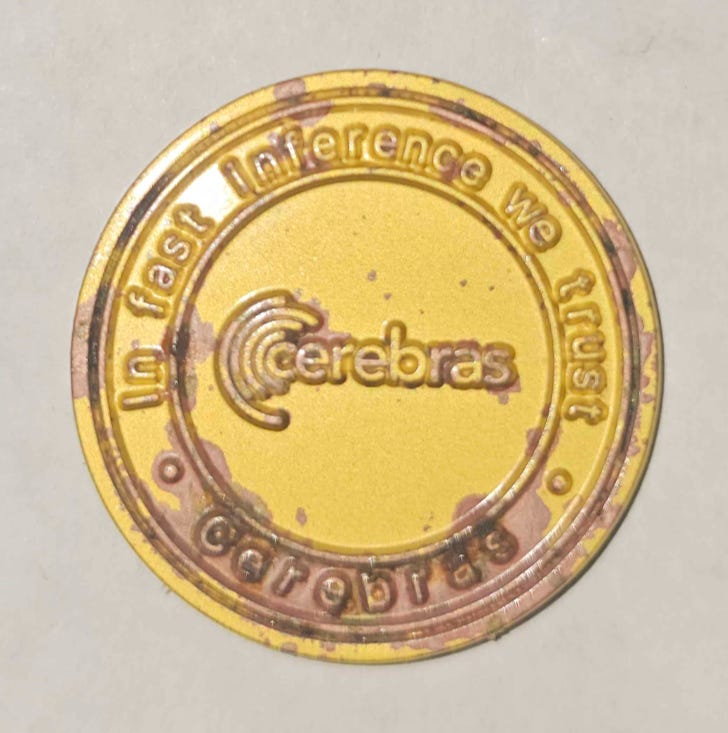
Last year Cerebras had a party at GTC which I crashed with someone else’s ticket. The food at that party was great by the way. Anyway, they had these fake gold “challenge coins” that say “In fast inference we trust.”
Chucked one of these coins somewhere and had to search my disaster zone of an apartment but found it. Thing has oxidized or something.
In a way, this stupid partially corroded coin is a metaphor for the company. The original goal of training is dead, tarnished by years of failure. But the underlying technological foundation is solid and can be re-used for ultra-high-speed inference.
An absurd, almost comical chain of events packaged into a tacky souvenir.
Feel like this is a suitable thumbnail.
Enjoy!
This does not make sense to me:
"Assume Cerebras has implemented weights using MXFP4 and QAT correctly.
In other words, weights as 8-bit int + some scale + some offset.
This 8.25-bit scenario is very optimistic"
MXFP4 is FP4 + shared block scale -> 4.25bit/parameter
maybe you mean MXINT8? that would use 8-bit int and is 8.25bit/parameter
If you look at openrouter Cerebras does not support max output length/total context for any model, so clearly they are having issues with context lengths, even at 200K, not 1M, but are still in the denial phase.
Saw this on Google News.